Sports Performance Analysis · September 2026
Internal · confidential · not for distributionTracking players from a football broadcast
A first pass at turning broadcast footage into player and ball positions in metres, so the tactical efficiency model has something to work from. Germany vs Denmark U21, 1080p30, measured on a 30 second window at t = 60–90 s.
01What this is
A working end-to-end pipeline on one window of one match, and an honest account of how far that is from a system.
Everything on this page was measured on one 30 second window of one broadcast. No figure here is quoted from a paper or a published benchmark, and none of it is a claim about a second match, a second ground or a second camera. Where a number would be flattering in isolation, the line underneath it says what it cannot show.
The footage is a broadcast feed, not a tactical wide camera, chosen deliberately because it is the harder case and the one a production system has to survive. It brings four properties that shape every decision below: the camera pans and zooms constantly, there are 4 hard cuts in 180 seconds, only part of the pitch is in shot at any moment so a full 22-player state is never directly observed, and a burned-in scoreboard sits over the top left of every frame.
The pipeline runs in stages, each writing its own JSON keyed by original frame index, each readable without re-running the stage before it: detect people, assign a team by shirt colour, join detections into tracks, find the ball, fit the pitch to the image, write positions in metres. The last file is the one that matters to a consumer and it has its own page: the data contract.
02What you are looking at
The broadcast on the left, and the same moment reconstructed in metres on the right.
On a phone, this one is small. It is a wide side-by-side, so it renders about a fifth of the height of your screen. Use it to check that IDs match across the two panels, then open the full-resolution broadcast overlay below for anything you actually want to look at.
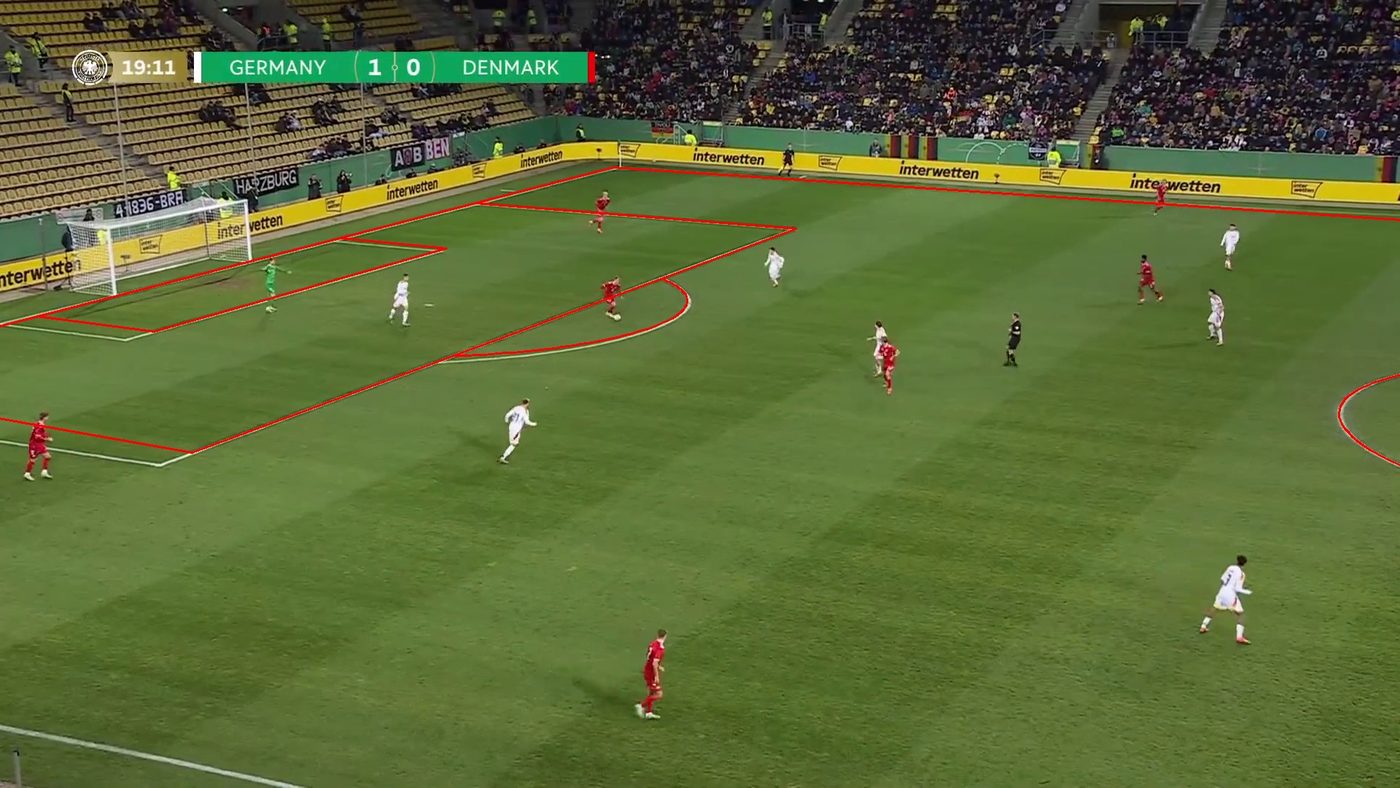
Open the full-resolution broadcast overlay →Track IDs match across the two panels, so a player can be followed from the broadcast into the pitch view and back. The right-hand panel is not a redrawing of the left: every dot is the bottom centre of a detection box pushed through that frame’s pitch calibration, so when a dot sits in the wrong place, the calibration is what is wrong. The ball carries a short trail and turns blue while its position is interpolated through an occlusion.
- Germany
- Denmark
- Official
- Goalkeeper
- Hi-vis — not a player
Detection runs at 10 Hz and each result is held across three frames for 30 fps playback,
so boxes step rather than glide. The number on a box is its track ID. A trailing ?
marks a low-confidence team assignment, and a box whose torso window straddles two people is
labelled unresolved rather than guessed.
Three things worth watching for, because they are real and they are visible. Hi-vis figures in front of the hoardings are tracked and labelled as non-players rather than dropped, so a detection problem stays countable. Around t = 83 s the camera whips across and the boxes briefly vanish and come back with new IDs. And a handful of dots in the pitch panel sit outside the touchline: those are kept and flagged, never clipped back onto the grass.
03What works, and the numbers that prove it
Six stages produce something usable today. Each figure names the window it was measured on, and each block ends with what that figure cannot tell you.
Player detection is solved at this camera distance
Stock yolo11m, imgsz 1280, conf 0.25 · 21–23 people per clean frame · no fine tuning
The off-the-shelf COCO person class finds every player, the keeper and the referee without any
training on football. Smaller models do not: yolo11n and yolo11s at the
same input size find 17, and yolo11m dropped to 960 px finds 16. Model size is
doing real work here; input size is doing more.
Team assignment is verified, one track at a time
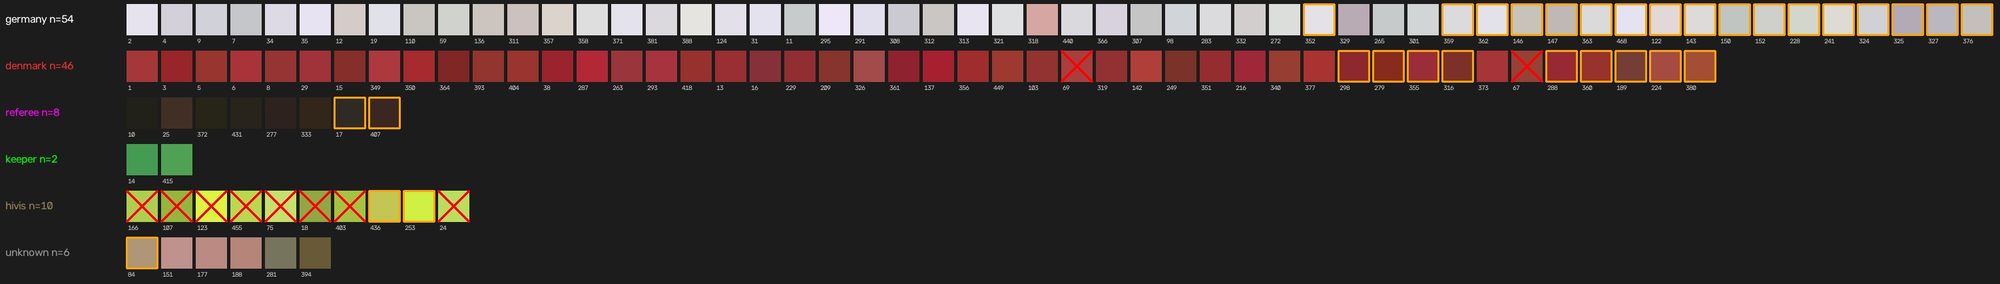
Torso colour in CIE LAB, aggregated per track · five classes · 8 detections of 5,607 left unresolved
Median LAB colour of a window across the chest, taken per detection and then per track, then k-means. The classes come out cleanly separated: Germany L 86.3, Denmark L 36.5 a* +43.2, referee L 16.3, keeper a* −42.5.
The verification was done by eye, track by track. On the first identification run all 110 stable tracks were opened as image crops and all 110 were correct. That run fitted 34 tracks to each kit, which is what about eleven a side fragmented into roughly three IDs apiece should look like.
The fifth class exists because of a failure. A four-class run reported twelve goalkeepers on a pitch that can hold two, because hi-vis bibs cluster with a green keeper kit. Hi-vis is now its own label and those tracks are carried through as non-players rather than deleted.
unknown and drew no icon at all. Re-running identification on the repaired tracks fixed
it: unresolved detections fell from 125 to 8 (0.14%). The current file has 56 tracks,
of which 51 carry a track-level label, 44 of them high confidence and 7 low, and 5
are labelled per detection. That set has not been re-checked crop by crop, so the
110-of-110 figure belongs to the earlier run and is not a claim about this one.
Track identity: 56 IDs down to 24, with zero identity swaps
t = 60–75 s · seven tracker configurations compared on identical detections
The default tracker produced 56 distinct IDs on a 15 second window holding
about twenty people on camera. The best configuration, tracktrack with appearance ReID
followed by an offline stitching pass, produces 24: zero colour-inconsistent tracks,
zero tracks under a second, and a median track length of 14.35 s of a 15 s
window. Of those 24 IDs, 14 were present from the first frame, 6 entered at the edge of the
picture, and only 4 are the tracker re-acquiring somebody it had already seen.
The mechanism is one parameter, and it was found rather than guessed. Of the 39 IDs
the default tracker invents mid-window, 39 of 39 are born on a detection below 0.70
confidence and 23 are below 0.45; median birth confidence 0.38. The better tracker ships
new_track_thresh: 0.70 and its median birth confidence is 0.75. Two things that sound
like the fix are measured and are not: appearance ReID on the default tracker made it
worse, 57 IDs to 70, and tuning its thresholds gave 37.
| Configuration | Raw IDs | After stitching | Swaps | Median track |
|---|---|---|---|---|
| botsort, the default | 56 | 31 | 0 | 12.6 s |
| botsort + ReID | 70 | 48 | 0 | 4.3 s |
| botsort, tuned thresholds | 37 | 31 | 0 | 11.9 s |
| tracktrack + ReID | 31 | 24 | 0 | 14.35 s |
positions_60_90.json were produced with the
default tracker: 126 raw IDs stitched to 56, with 2 colour-inconsistent tracks surviving and a median
track length of 6.5 s. Re-running the published window under the recommended configuration is a
pending job, not a finished one.
Ball tracking: 85.3% positioned, and the gaps are occlusion rather than loss
300 sampled frames · 209 detected, 47 interpolated, 44 gaps
The ball is 10 to 19 pixels wide here, so no single confidence threshold solves it. The design is recall first: generate candidates cheaply in one inference pass at conf 0.02, add white-blob candidates for frames the detector misses entirely, throw away anything off the pitch polygon or inside the scoreboard box, then do all the precision work offline with a motion model. A crowd false positive does not stay on a plausible trajectory; a ball does.
The gaps were checked rather than assumed. All 44 gap frames have the ball in contact with a player, so the misses are occlusion, not random loss. Interpolation is applied only to short skipped runs inside a linked segment, never across a re-acquisition where nothing vouches for the positions in between, and every interpolated frame is flagged in the data.
Pitch calibration: 3.68 px residual, propagated to all 300 frames
One key frame pinned by hand · 92.8% of on-surface line ink explained · median 93.1% across the window
A human names four to six markings with a rough two-point guide on one frame; everything after that is measured. Each guide is refitted to the ink it contains, the homography is solved from the crossings, and iterative closest point pulls the whole model pitch onto the line mask. That frame is then carried across the window by tracking grass features between consecutive frames, and every frame is re-seated on its own markings rather than trusting the chain.
Two independent checks agree. The centre circle, whose 9.15 m radius is fixed by Law at every ground, back-projects to 9.12 m. And the reconstruction was checked against something the fit never saw: turning detection boxes into player heights gives a median of 1.75 m over 297 boxes across 16 frames.
Positions in metres, with the awkward rows kept
5,607 player rows + 300 ball rows · 99.1% inside the pitch · full contract
A player’s position is the bottom centre of the detection box mapped through the ground plane, not the box centre, which is roughly chest height and projects metres further from camera than the player is standing. Positions outside the pitch are kept and flagged rather than clipped, because a player over the touchline, a steward behind the hoardings and a calibration error all produce out-of-bounds coordinates, and clipping silently turns the last two into plausible-looking football. Non-players are carried through with their label for the same reason.
04What does not work yet
None of these is a detail. Each would have to be closed before positions from a full match could be trusted, and two of them are unbuilt rather than imperfect.
Generalisation is unproven, and the one test we ran failed
The same tracker configuration on a different 15 second window of the same match gives 37 IDs after repair, not 24, and 14 detections per frame against 20. The 14 is not a recall failure: the camera has zoomed tight on a goalmouth attack with seven people in shot, then pulls back out to wide. There is no cut anywhere in that window.
So the headline tracking result is a result about one window. A single window is not evidence, and the second window we tried is 50% worse.
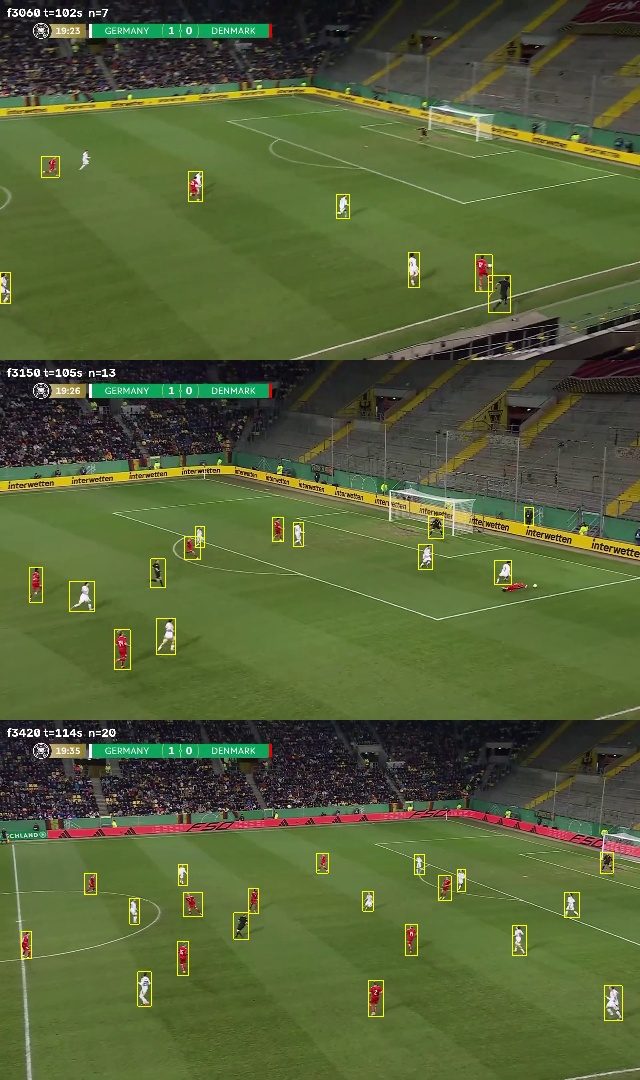
The pitch mask rejects nothing, so about a third of the surplus IDs are not players
A yellow-bibbed ball boy seated on the advertising hoardings is re-acquired under six separate IDs. A steward in black behind the boards holds a single ID for 232 detections. The pitch polygon is computed and is used by the ball stage, but the player tracking stage does not filter on it: on the comparison runs, 0 detections were rejected as off-pitch.
This is cheap to fix and it inflates every ID count on this page. It is left visible rather than quietly filtered, because a detection problem that has been hidden cannot be counted.
Identity across camera cuts is not built
There are 4 hard cuts in 180 seconds of this footage, in two brief pairs, and every one resets player identity completely. Nothing in the pipeline attempts to carry a player across a cut. For a tactical model this is the difference between a possession chain and a pile of fragments, so it is a requirement rather than an extension.
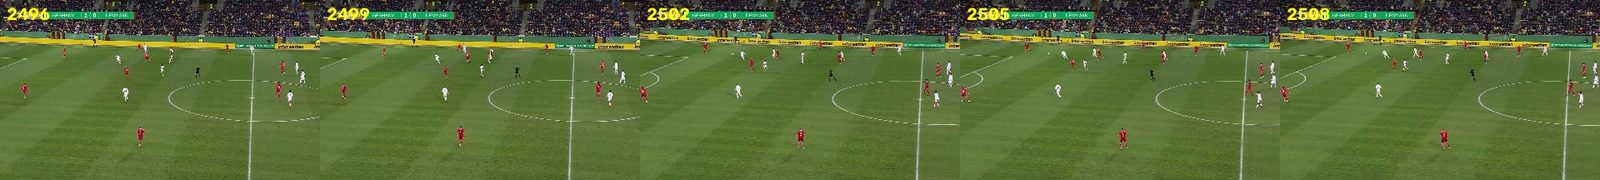
Worth knowing: the worst single event in this window is not a cut. A fast camera pan at t = 83.4 s collapses detection from 20 people to one on a single motion-blurred frame, and every ID in the window is reborn on the other side of it. A pan-compensated stitching pass recovers 11 of the 15 new IDs that event creates.
No ground truth exists, so nothing here has a measured recall
Every figure on this page is a self-consistency figure: how many boxes, how many IDs, how much line ink the model explains, how many positions land inside the pitch. Not one of them is a comparison against a known answer, because there is no labelled set for this footage.
Self-consistency is not truth, and it can move the wrong way. This project already produced a ball tracker whose coverage and smoothness both improved as the answer got worse. A hand-labelled minute would convert most of this page from plausible into measured, and it is the cheapest thing on the list below.
Pitch width was assumed, not fitted
Length was fitted as a free parameter and reads 102 m at this ground. Width was not: 68 m is an assumption carried straight into every coordinate. Near the touchlines that is worth roughly 1.5 m of uncertainty in the across-pitch direction, which is a full body width in exactly the region where wide players and the offside line live.
Lens distortion bows the lines and no single homography can absorb it
The painted markings in this footage bow by 1 to 6 px of sagitta over their visible length: the halfway line by 3.2 px, the penalty-area side line by 5.6 px. A homography maps straight lines to straight lines, so it cannot represent that, and the residual is absorbed as a small error spread across the fit. It also means a single homography cannot separate a genuinely short pitch from an uncorrected lens, which is a caveat on the 102 m figure as well as on the residual.
A broadcast feed never shows all 22 players
Between 16 and 23 of the 22 players are in frame at any moment. A full team state therefore has to be inferred, not observed, and nothing here attempts it. Whether the tactical model needs all 22 every frame, or is satisfied with the players in shot plus the ball, changes the difficulty of this project by a large factor, and it is the first open question below.
05What it would take to run a full match
The compute is not the obstacle. The obstacle is the three unbuilt stages above.
Measured cost, on the development machine
| Model | Input size | Seconds / frame | People found |
|---|---|---|---|
| yolo11n | 1280 | 0.26 | 17 |
| yolo11s | 1280 | 0.50 | 17 |
| yolo11m | 960 | 0.60 | 16 |
| yolo11m | 1280 | 1.23 | 19–23 |
CPU-only Windows box, 1080p frames. At 10 Hz a 90 minute match is 54,000 frames: about 18 hours here, and under 10 minutes on one rented L40S-class GPU. Nothing in this pipeline needs a standing GPU, and the same shape as the hockey work applies — inference on rented pods, artefacts and clips to R2, review pages on Pages.
Sampling rate is a quality lever for some trackers and not for others, and getting this backwards costs three times the compute.
On the default tracker, sampling at 30 Hz instead of 10 Hz changed the ID count from 56 to 57. Tripling the compute bought nothing, which is the most useful negative result of the work. But the recommended tracker is the opposite: 24 IDs at 30 Hz against 26 at 10 Hz, and the 10 Hz run introduced identity swaps the 30 Hz run did not, because its association is driven by box overlap and a three-frame gap under a fast pan moves a box most of its own width.
So the honest statement is tune the stride, not the thresholds — and re-measure the stride whenever the tracker changes. A full match under the recommended configuration is 162,000 frames, three times the figures above.
What has to be built before a full match is worth running
- Re-identification across cuts. Required, not started. Four cuts in three minutes, every one resetting identity.
- Off-pitch rejection in the player stage. The mask already exists and the ball stage already uses it. Cheapest item on the list, and it removes roughly a third of the surplus IDs.
- Calibration without a human on the first frame. The automatic line-identification search does not converge on this footage, and the diagnosis is specific: the “constant x” and “constant y” line families do not separate by image angle here, so no angle threshold can sort them. The production answer is a trained pitch-keypoint model in the style of the SoccerNet calibration work, which predicts named landmarks directly and sidesteps identification entirely. It needs a GPU and a labelled set. Two cheaper things to try first: local refinement of a rough homography against the line mask, and using the centre circle as a conic, which is a very strong constraint that no straight-line method uses.
- A hand-labelled minute. Converts most of section 03 from plausible into measured, and is the only way any recall figure on this page becomes real.
- A second match, at a second ground. The turf reference is sampled from the frame rather than hardcoded specifically so that it can survive a different stadium, a day game or a different grass treatment — but that is a design intent, not a measurement.
Open questions for the data side
- Does the tactical model need all 22 players every frame, or the players in shot plus the ball? This changes the difficulty by a large factor. Ball position is already confirmed as required.
- What sampling rate does the model want? 10 Hz is cheap, and on the evidence above it costs nothing on the default tracker and two IDs on the recommended one.
- Is jersey-number identification required, or is “team plus a stable track ID” enough? Numbers are a per-track cost and a separate model.
- Is there any access to a tactical camera or a club-provided feed? Almost everything on this page gets easier if the whole pitch is always in frame.
- How should the model consume a ball gap during occlusion: a marked gap, or an interpolated position with a confidence? The data carries the flag either way, so the model should choose rather than inherit our default.
06The traps
Seventeen things that looked right and were not. These are the transferable part of the work: most of them are not about football at all, and every one would cost the time again.
Seeing the pitch
The advertising boards are the same green as the grass
- Looked right
- The standard recipe, “take the largest green connected component”, produced a mask that covered the pitch.
- Actually true
- It had merged the pitch with the perimeter hoardings and run up into the crowd. Hue alone does not separate them: pitch sits at hue 40–45 with a standard deviation under 10 and saturation 135–158, the green boards at hue 64–66 with sd 40–64 and saturation 79–92.
- Caught by
- Measuring hue tightness and saturation region by region instead of trusting hue. The turf reference is now sampled from the bottom centre of the frame rather than hardcoded, which is what should let it survive a different ground.
Scanning up each column stops at the players’ feet
- Looked right
- Walk up each column of the image until the green stops, and that is the top edge of the pitch. A sensible, cheap rule.
- Actually true
- It stops at the first player, carving a wedge out of the mask exactly where each player is standing — which is the one place the mask has to be right.
- Caught by
- Looking at the mask rather than at the numbers. The column scan is now a blurred green density over a window: a player is narrow and the pitch is wide, so density survives a person and does not survive the boards.
White thresholding returns the shirts, not the lines
- Looked right
- Pitch markings are white, so threshold on white. The threshold returned thousands of pixels and 24 clean Hough segments on the test frame.
- Actually true
- Under floodlights the paint is dimmer than the white kit. None of the 24 segments was a pitch marking: they were Germany’s shirts and the goal frame.
- Caught by
- Drawing the segments back on the frame. The fix is a morphological white top hat, which finds whatever is locally brighter than its surroundings — what a painted line is, regardless of how that part of the pitch is lit — with the player boxes masked out first, since a white shirt is exactly what a top hat would otherwise keep.
The strongest line in the frame is not a pitch marking
- Looked right
- Take the highest-contrast long edge and call it the touchline. It fits beautifully: low rms, thousands of supporting pixels.
- Actually true
- There are metres of run-off behind the goal line and outside the touchline, and the strongest edge in the image is the pitch-to-hoarding boundary, which is not on the pitch model at all. At this ground the far touchline is not even visible. Using that edge puts every player metres out, and the fit still looks perfect.
- Caught by
- Reprojecting the whole pitch model rather than scoring the individual line. Touchlines are now excluded from the fit entirely and their position is only ever an output of it, never an input. Any calibration method that trusts line strength will take this bait.
Geometry that scores well and is wrong
A degenerate homography scores a perfect 0.00 px
- Looked right
- Mean reprojection error 0.00 px, every model sample reported in frame. The best score in the entire search.
- Actually true
- The homography had collapsed the whole pitch onto a single point, and that point happened to land on a line pixel. Distance to the nearest line is zero for every sample because every sample is the same sample.
- Caught by
- Guarding on the geometry rather than the score: the projected pitch outline must be a convex, correctly wound quadrilateral with real area and real spread, and the horizon implied by the homography must sit above the visible pitch. Those checks cost nothing and remove most of the search space.
A one-way distance score rewards shrinking
- Looked right
- Tiny mean distance from every projected model point to the nearest detected line, and a claim that 1,077 of 1,100 model points were in frame.
- Actually true
- The shot showed about a third of the pitch. The optimiser had squeezed the model until every projected point landed somewhere on some long line, which is free marks in a one-way metric. An optimiser walks downhill into this trap harder than a search does.
- Caught by
- Scoring both directions: model-to-image distance and the share of detected line ink the model actually explains. A shrunken model explains almost none of it.
0.42 px per step, 300 px wrong by the end
- Looked right
- Carrying the calibration forward frame to frame gave a median frame-pair residual of 0.42 px on about 390 inliers. Excellent at every single step, and every step was checked.
- Actually true
- Chaining 299 of those walks the pitch model roughly 300 px off the markings by the end of the window. The share of pitch ink explained falls from 93% to 13%. The camera zooms out over these 30 s and a multiplicative scale error compounds.
- Caught by
- Measuring the end of the chain against the image instead of the per-step residual. Every frame is now re-seated on its own line mask and the chain is used only as an initial guess for the next frame, which is the one job it is reliable at. A per-step residual well under a pixel says nothing about where the 300th composition lands.
The burned-in scoreboard cancels the camera pan
- Looked right
- Track features between consecutive frames to recover the camera motion. Plenty of features, plenty of inliers, low residual.
- Actually true
- The scoreboard graphic does not move at all, which makes it the single worst feature source in the frame: it drags the estimate toward the identity transform and quietly cancels the pan, while the crowd and the players move independently of the ground plane and corrupt it in other directions.
- Caught by
- Dropping everything above the projected far touchline, which removes the crowd, the boards and the score bug in one test, and dropping the tracked player boxes with a margin. What is left is grass, which is the only thing that moves exactly with the ground plane.
This pitch is not 105 metres long
- Looked right
- Fit the penalty area and the halfway line together on the regulation 105 m pitch. Residual 4.95 px, which reads as a good fit.
- Actually true
- Calibrating against both at once is an assumption about pitch length, and this ground is about 102 m. The instrument that reads the error is the centre circle, whose 9.15 m radius is fixed by Law everywhere: at 105 m it back-projects to 9.36 m with a 5.73 px median residual, at 102 m to 9.12 m with 0.00 px, and the overall fit bottoms out in the same place at 3.68 px.
- Caught by
- Sweeping the assumed length instead of inheriting it, and checking against a dimension the Laws fix rather than one the groundsman chooses. Anything downstream that assumes the regulation length is roughly 1.5 m out near the halfway line.
The widest point of a projected circle is not the projection of the widest point
- Looked right
- The centre circle and the penalty arc are obvious landmarks, so let the operator click the widest point of the circle and the apex of the arc.
- Actually true
- A circle projects to an ellipse, and the extreme point of that ellipse is not the image of the extreme point of the circle, so nobody can click it correctly. Measured on a real fit: the circle’s widest point came out at 23.2 px of error and the arc apex at 17.3 px, while every intersection landmark sat under 7 px.
- Caught by
- Per-landmark error reporting, which made three points stand out from thirty. Only points defined as the crossing of two features survive projection, so those are the only ones the calibration tool offers.
Identity
Recording only confirmed tracks hides the tracker’s own failure
- Looked right
- Store the detections the tracker has accepted and given an ID to. The output was clean, well formed, and nothing about it looked wrong.
- Actually true
- On one frame it stored 1 player where the detector had seen 23. The tracker’s worst moment was invisible in the tracker’s own output, by construction.
- Caught by
- Recording every detection with
"id": nullwhen unconfirmed, which makes the failure countable. This is the hockey pipeline’s coverage is availability, not correctness rule, and it generalises: a metric computed only over the rows a stage succeeded on cannot measure that stage.
One track ID, two different players
- Looked right
- The tracker fragments people into too many IDs, so a lower ID count is a better result. Every change was scored that way.
- Actually true
- It also merges two people into one ID. Track 110 runs 34 consecutive detections on a Denmark player and then 66 on a Germany player; track 318 is 15 red then 16 white. Sixteen tracks disagree with themselves about their own player’s shirt colour more than 15% of the time. So a distinct-ID count cannot distinguish the two faults: merging fragments lowers it, and conflating players lowers it too.
- Caught by
- Shirt colour, which was already computed for every track and is free. Colour-inconsistent tracks are split before anything is merged, cross-kit merges are refused outright, and the two faults are now reported as separate columns. Both swaps were confirmed by pulling the rendered frames back out of the video at each end, and reproduce exactly against an identity file fitted independently.
A player went invisible because two stages ran in the wrong order
- Looked right
- Identify teams, then repair the tracks. Both stages had been verified on their own, the labels were 110 of 110 correct, and the joined output was well formed.
- Actually true
- Stitching happens after labelling, so a merged track inherits the label of whichever fragment was
its root — and a root can be a two-sample fragment. One Denmark player with 117
detections came out
unknownand drew no icon on the pitch view at all. The stage boundary was correct; the stage order was not. - Caught by
- Watching the rendered pitch view and noticing a player who was not there. Re-running identification on the repaired tracks took unresolved detections from 125 to 8. A verified stage feeding a verified stage is still not a verified pipeline.
Twelve goalkeepers
- Looked right
- Four colour classes — two kits, referee, keeper — cleanly separated in LAB space, with every track confidently assigned.
- Actually true
- It reported twelve goalkeepers on a pitch that can hold two. Ball crew and stewards in fluorescent bibs standing in front of the hoardings cluster with a green keeper kit. The general lesson: a colour class absorbs anything of that colour, and a broadcast frame contains a lot of people who are not players.
- Caught by
- Checking the count against what is physically possible. The separation is large once looked for: the two real keeper tracks sit 1.77 from the green cluster centre and the other ten sit 26.6 to 58.3, and all ten are independently too small for their distance from camera against a fitted perspective model. Hi-vis is now its own class.
Appearance ReID made the tracker worse
- Looked right
- Fragmentation is an appearance problem, so switching on appearance re-identification should fix it. It is the obvious lever and it is a supported option.
- Actually true
- On the default tracker it went from 57 IDs to 70, and sub-second tracks from 17 to 28. Tuning that tracker’s thresholds instead gave 37, which is better but still worse than simply changing tracker. ReID helps on the other tracker; the lever is not transferable.
- Caught by
- Running all seven configurations over identical detections so the only variable was the tracker, and diagnosing the real cause separately: 100% of the surplus IDs are born on detections below 0.70 confidence. Do not assume appearance helps. Measure it.
The ball, and metrics that flatter themselves
More input pixels made the ball harder to detect
- Looked right
- The ball is 10 to 19 px wide, so it is a small-object problem, so feed the detector more pixels. Raise the input from 1280 to 1920.
- Actually true
- Confidence on the test frame collapsed from 0.57 to 0.11. The detector was trained at 640, so upscaling pushes a 12 px ball out of the size distribution it learned. More pixels is not better here, which is the opposite of the intuition.
- Caught by
- Probing four frames at both input sizes before committing to either. The operating threshold was set the same way: the ball measured 0.57 / 0.68 / 0.69 on three frames and 0.03–0.08 on a fourth where it sat at a player’s feet, so candidate generation had to run below 0.03 or lose that whole class of frame by construction.
Coverage and smoothness both improved as the answer got worse
- Looked right
- 100% ball coverage, and a smoothness check over consecutive detected frames that passed. Two independent healthy metrics.
- Actually true
- The path was jumping from (914, 374) to (1915, 754) to (462, 243) across consecutive sampled frames and then interpolating over its own jumps. Coverage was 100% because the interpolation filled everything, and the smoothness check skipped precisely the bad frames because they were separated by gaps. The root cause: a flat “miss” state carries no memory of where the ball was, so re-entering from it cannot be gated on anything.
- Caught by
- Watching the rendered ball track. The rebuild makes states pairs of observations so the cost is an acceleration residual rather than a position one — the camera pans, so a static white mark on the pitch moves frame to frame just as the ball does, but it cannot keep matching a constant-velocity prediction while the ball changes speed. Gaps are now crossed only within a distance and frame-count cap; when the ball genuinely goes away the path pays a restart cost and the gap is reported as a gap rather than bridged. Interpolation never spans a re-acquisition, and is flagged in the data.
The thread running through half of these. Six of the seventeen are not bugs in football code at all — they are a score that improved while the answer got worse. A degenerate fit scoring 0.00 px, a one-way distance rewarding a shrunken model, a per-step residual under a pixel hiding a 300 px drift, an ID count that cannot separate two opposite faults, a coverage figure computed only over the frames that succeeded, and a smoothness check that skipped exactly the frames that were wrong.
Every one was caught the same way: by looking at the rendered artefact, or by checking the number against something physical that the fit never saw — a 9.15 m radius, a 1.75 m player, a pitch that can hold two goalkeepers.